


Instagram answers my flat, not my server.
- Kind
- Essay, 2026
- Read
- 9 min
- Built in
- One day
- Runs on
- A Mac mini at home
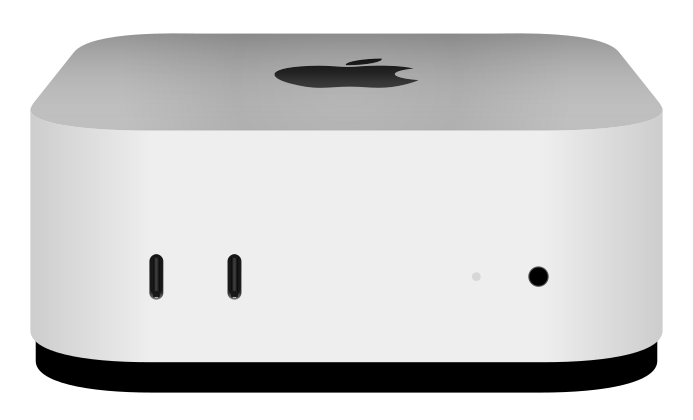
On 14 October I shipped three things to WhatWeCook’s import in one day. A Mac mini in our flat started fetching Instagram videos. I turned off a setting in yt-dlp that would have let a post link redirect the fetcher onto a device on my own network. And I replaced a request that was held open for twenty seconds with short calls every three.
Paste a reel into WhatWeCook and you get a recipe back: title, ingredients, steps, in your language, with a photo, in about fifteen to forty seconds. The part that makes that work on Instagram is not a model. It is a computer in my flat.
That is the short version. This post is how it actually works, including the two things I got wrong the same day I built it, and the one I am still carrying.
Why the server gets nothing
Instagram, TikTok and YouTube answer a home connection. They do not answer a datacentre. My site runs on one, so for the hardest half of what people paste in, the import was knocking on a door that does not open for it.
Some of it worked. Instagram’s official API gives you the caption and the video for creator and business accounts, roughly their last four hundred posts. A crawler preview gives you the caption when the API cannot. TikTok hands over the full caption through oEmbed. YouTube blocks datacentre addresses, so there are four things to try in order and each gets seven seconds.
And then there are reels with licensed music, where there is no video to be had that way at all. What comes back is a caption, which is often a mood and three emojis, or nothing but a title.
When that happens the app saves a title and says so. It does not let a model write a recipe from a name, which it would do cheerfully and convincingly. An honest empty draft is not much use to the person who pasted the link, but it is a great deal better than a confident invention with their dinner riding on it.
Which is the actual problem with reels. The amounts are not written down anywhere. They are said out loud, or they are on the screen for a second and a half.
The Mac mini does the fetching
So the fetching moved to a machine that gets answered. The Mac mini at home asks my site for work every three seconds. That call is also its heartbeat, so there is nothing else to keep alive: an import only waits for the worker if it checked in within the last ninety seconds. If the mini is off, nobody waits. The import takes the old path and nothing about the app gets slower.
Per job it gets two things: a URL, and a token that can upload exactly one mp4, once, within ten minutes. It runs yt-dlp for the full caption, up to forty comments and the video at 720p or less. If the file is bigger than 44 MB it is re-encoded down to 480p. If it is still too big it is dropped, and the caption and comments go on without it. Gemini needs the picture and the sound, not 4K.
Then it uploads, reports done, and the server deletes the video as soon as it has been watched. The mini upgrades yt-dlp once a day on its own, because a stale yt-dlp is the most likely reason any of this stops working.
Watching is not reading
Gemini Flash watches the video together with the caption and the creator’s own comments. Only theirs. Other people’s comments under a recipe reel are noise, and some of them are confidently wrong about what is in the pan.
The part I am happiest with is not the watching. It is that every ingredient comes back saying how it is known.
- saidSpoken in the voice-over.
- on screenWritten on the video, often for a second.
- captionIn the post's own text.
- commentAdded by the creator underneath, not by anyone else.
- seenVisible in the shot, like a tin going in.
- estimatedJudged from the picture. Keeps its ≈ everywhere.
An amount judged from the picture gets a ≈ in front of it, and that mark has to survive everything downstream. Extraction keeps it. Translation keeps it, and a translation that changes the number of ingredients or steps is rejected outright, because a translator that quietly merges two lines has edited the recipe.
What it changed
I measured it on nineteen reels I had already saved, read the old way and then again with the video.
Recipes that came back with no ingredients at all went from six to one. Recipes with a cooking time went from eight to eighteen. The ingredients found across all nineteen went from 187 to 263.
Watching a video costs about nine tenths of a cent. The text side of an import is around two cents and the photo is where the money goes, eight to ten if it needs a new one. The reading is cheap. I expected the opposite when I started.
I want to be honest about something
Two of the three things I shipped on 14 October were fixing the first one.
The worker started out holding a request open for twenty seconds at a time, which is the obvious way to do long polling and the wrong way to do it on a serverless platform. It kept a function running day and night to listen to silence, roughly ten to fifteen euros a month. Short calls every three seconds cost fractions of a cent a day and do the same job.
The other one was worse. yt-dlp has a generic extractor that will follow a link to wherever it goes, and the worker runs inside my flat, on my network. A post link that redirected to another host could have had it fetching a device at home. A security review caught it and I turned the extractor off the same day, with a host allowlist and the URL never passed through a shell. Eight days later I did the matching fix on the server: a fetch now connects only to the addresses that were checked, so nothing can swap them underneath it.
Both of those are the sort of thing you ship when you are moving fast on your own. I am not going to pretend the review was my idea of a good Tuesday.
The one I am still carrying is simpler: it is a computer in my flat. A power cut, an OS update or a bad upgrade and the best half of the import quietly goes back to the old path. For an app my friends and my family use, I can live with that. If people were paying me, I could not.
And the honest frame around all of it: the import got much better at reels. That is not the same as people importing reels. Building something and having it used are two different claims, and I have written a whole post about getting the first one and not the second.
The model comes last
None of this starts with a model, and that is the design, not an economy measure.
If a page has a real recipe in its structured data, with a title and at least one ingredient, it is taken exactly as it is. No model, no rewriting, no improving the photo the blog already chose. Most recipe blogs have this. If it does not, the readable text gets stripped of navigation and newsletter boxes, capped, and then a model extracts from it. If a creator’s caption says the full recipe is on their site, up to two of those links are followed, and if one of them has a proper recipe, the creator’s own version wins over anything we worked out from the video.
Anything read from a picture is read twice, in parallel, and kept only if the two agree: both confident, counts within one of each other, and the ingredient words overlapping by at least 0.35. That number is not a feeling. Correct reads overlap between 0.48 and 0.66, invented ones between 0.04 and 0.19, and the threshold sits in the gap.
The reason it works is the useful bit. A model will tell you it is highly confident about half the time on a page it cannot read. It cannot invent the same recipe twice.
Whether this works for you
If you are fetching anything that lives behind a bot wall, the shape transfers. Put a machine with a home connection on the fetching, give it a heartbeat so the rest of your system only waits for it when it is actually there, and hand it one narrow upload token per job rather than a key to anything.
Tag every field with how it is known, and show that to the person. Read anything visual twice and call a disagreement a failure rather than picking a winner. Make each step its own call, because a progress bar animating over one long call is a lie and it feels slower than the truth does. Cache on the source, never on what somebody edited afterwards. Keep the evidence of every failure: almost every bug I have fixed in this pipeline was found by looking at the pictures it could not read.
And put a human at the end of it. Nothing saves until the person taps save, and the form tells them what is missing instead of apologising. That gate is where the trust comes from, and it is the cheapest part of the whole thing.
If you have questions, ask me.
Everything above runs on a platform I can deploy to in forty seconds, except the one machine that makes it work, which is on a shelf at home.